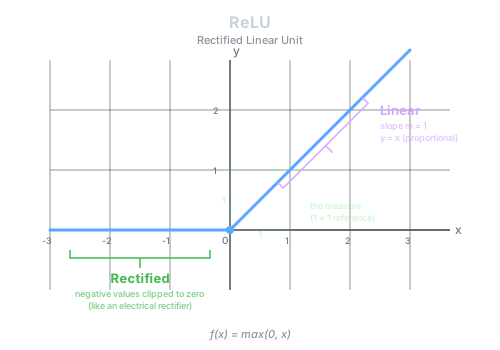
Rectified Linear Unit
The name ReLU is a metonymy—a figure of speech where a thing is called by the name of something associated with it. In the neural network literature of the 1980s, individual neurons were called “units”—processing units, hidden units, output units. When Nair and Hinton (2010) introduced a unit whose activation function was the rectified linear function max(0, x), they named the unit: a Rectified Linear Unit.
Through metonymy, the name of the unit became the name of the function. Today, “ReLU” refers to max(0, x) itself, and the word “unit” in the acronym has become invisible—absorbed into the proper noun. When we write “ReLU activation,” we are saying “Rectified Linear Unit activation”—redundant in the same way as “ATM machine.” The unit is the activation; the activation is the unit.
In the diagram above, “Rectified” labels the zero-clamped region (x < 0) and “Linear” labels the identity region (x ≥ 0). The “Unit” is not a region of the graph—it is the neuron that uses this curve as its activation function.
| Operation | ReLU (bpd_relu) |
|---|---|
| Formula | f(x) = max(0, x) |
| Category | Piecewise linear |
This is the backend-neutral op_expr fact that specifies the operation. The same term is lowered to LLVM IR, CUDA C, MLIR, and every other backend — one specification, many targets.
op_expr(bpd_relu,
    sel(is_nan(var), var,
        sel(ge(var, const(0.0)), var, const(0.0)))).
| Backend | CUDA C (cuda_c) |
|---|---|
| Target | gpu |
| Description | CUDA C source code. Compiled with nvcc. |
This is the actual CUDA C emitted by our Prolog/Logtalk toolchain for this operation. Every instruction was generated from a declarative op_expr specification — no hand-written assembly.
/* GENERATED from robust_op_match(bpd_relu) — canonical fact (op_expr AST).
 * formulation: x != x ? x : (x >= 0 ? x : 0.0f)
 * reference: pytorch_mkl  tier: gold
 * C++/CUDA backend. Compile: nvcc -arch=sm_61. Run on the P4.
 */
#include <cstdio>
#include <cstdint>
#include <cuda_runtime.h>

__global__ void relu_kernel(const float* x, float* c, int n) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) { float v = x[i]; c[i] = ((v != v) ? v : ((v >= 0.0f) ? v : 0.0f)); }
}

static float relu_ref(float v) { return ((v != v) ? v : ((v >= 0.0f) ? v : 0.0f)); }

int main() {
    printf("=== GENERATED-FROM-FACT C++/CUDA relu on Tesla P4 ===\n\n");
    const int EDGE=9; const int n=1024;
    float xh[n];
    xh[0]=0.0f; xh[1]=-0.0f; xh[2]=NAN; xh[3]=-1.0f; xh[4]=1.0f;
    xh[5]=1.17549435e-38f; xh[6]=-1.17549435e-38f; xh[7]=3.4e38f; xh[8]=-3.4e38f;
    for (int i=0;i<n-EDGE;i++){ float t=(float)i*0.013f-6.6f; xh[i+EDGE]=t*((i%3==0)?-1.0f:1.0f); }
    float *xd,*cd; cudaMalloc(&xd,n*4); cudaMalloc(&cd,n*4);
    cudaMemcpy(xd,xh,n*4,cudaMemcpyHostToDevice);
    int blk=256, grd=(n+blk-1)/blk;
    relu_kernel<<<grd,blk>>>(xd,cd,n); cudaDeviceSynchronize();
    float ch[n]; cudaMemcpy(ch,cd,n*4,cudaMemcpyDeviceToHost);
    int diffs=0, first=-1;
    for (int i=0;i<n;i++){ float want=relu_ref(xh[i]);
        uint32_t wb=*(uint32_t*)&want, gb=*(uint32_t*)&ch[i];
        int eq = (wb==gb) || (isnan(want)&&isnan(ch[i]));
        if(!eq){ if(first<0) first=i; diffs++; } }
    if(diffs==0) printf("  *** 0 differences — BIT-IDENTICAL (%d elems) ***\n", n);
    else { printf("  %d differ. first idx %d x=%g\n", diffs, first, xh[first]); return 1; }
    return 0;
}
This (operation, backend) pair has not yet been measured. When the backend emitter and verification infrastructure are ready, this cell will be tested against the PyTorch reference.
